

Lovable Editor’s Pick
Describe an app in plain English, get a working full-stack product
Curated listings are not ranked, so they cannot be voted on.
Browse by category
All categoriesBrowse by platform
All platformsResources
Latest postsTurn any website into clean, LLM-ready structured data
Curated listings are not ranked, so they cannot be voted on.
npm install @mendable/firecrawl-js 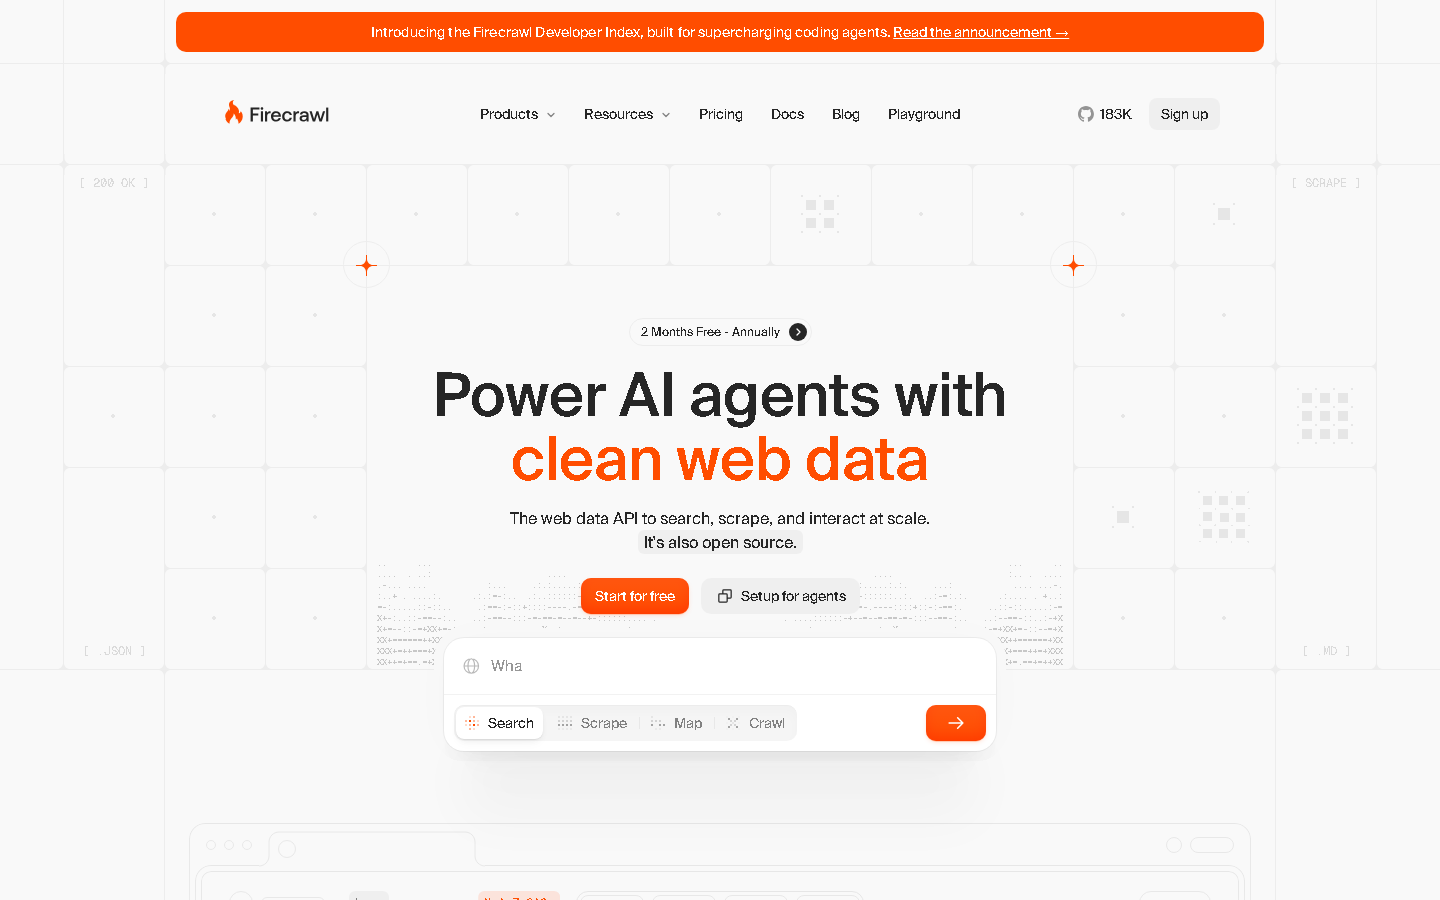
Firecrawl crawls, scrapes and extracts web pages into markdown or JSON that AI agents can consume directly, handling JavaScript rendering, proxies and rate limits. A single API call replaces a fragile homegrown scraping stack. The core engine is open source and self-hostable.
A single call returns a page as markdown, structured JSON or a screenshot, handling the rendering and cleanup that usually breaks a homegrown scraper.
Crawl follows links across a site with configurable depth and filtering, and Map returns a site's URLs, so you can pull a documentation set or a catalog without hand-listing pages.
Search queries the web and returns full page content rather than just links, and Interact scrapes a page and then acts on it using AI prompts or code for flows behind a click.
Document parsing covers PDF, DOCX and HTML files, which keeps file-based sources in the same pipeline as web pages instead of a second tool.
Official SDKs cover Python, Node.js, Go, Rust, Java and Elixir on top of the REST API, and an MCP server connects Firecrawl to tools such as Cursor and Claude.
Developer building a RAG pipeline
Turn a documentation site into clean markdown with one crawl call rather than maintaining selectors that break on every redesign.
AI startup team
Give an agent live web access through the search and scrape endpoints, and keep costs visible through the per-page credit model.
Growth or research analyst
Collect competitor pricing pages on a schedule and get structured JSON back that drops straight into a spreadsheet or warehouse.
Raised an oversubscribed $14.5M Series A in August 2025 with 350,000+ registered developers and customers including Zapier, Shopify and Replit.
Firecrawl is an API that turns websites into data an LLM can use. It scrapes pages into markdown or JSON, crawls entire sites, maps URLs, searches the web with full content, parses PDF and DOCX files, and handles the rendering and blocking problems that usually sink a homemade scraper.
There is a free tier with 1,000 credits a month. As of September 2026 the pricing page lists Hobby at 16 dollars a month for 5,000 credits, Standard at 83 dollars for 100,000, Growth at 333 dollars for 500,000 and Scale at 599 dollars for 1,000,000, all billed annually, with Enterprise custom. One credit covers one page on a basic scrape, crawl or map.
The core engine is open source on GitHub and can be self-hosted, and the hosted API removes the need to run proxies and browsers yourself. To start in JavaScript, install the SDK with npm install @mendable/firecrawl-js, or use pip install firecrawl-py for Python. Official SDKs also cover Go, Rust, Java and Elixir.
Version history appears here once the maker claims this listing and starts posting releases.
Comments open with submissions.
Describe an app in plain English, get a working full-stack product
Curated listings are not ranked, so they cannot be voted on.
Open source link management and attribution for modern marketing
Curated listings are not ranked, so they cannot be voted on.
Self-hosted, open source alternative to Vercel, Heroku and Netlify
Curated listings are not ranked, so they cannot be voted on.